Web scraping API for clean data
Send any URL. Get clean Markdown or JSON back, ready for your app or AI agent.
Drag across the page to see the clean text Spicrawl keeps.
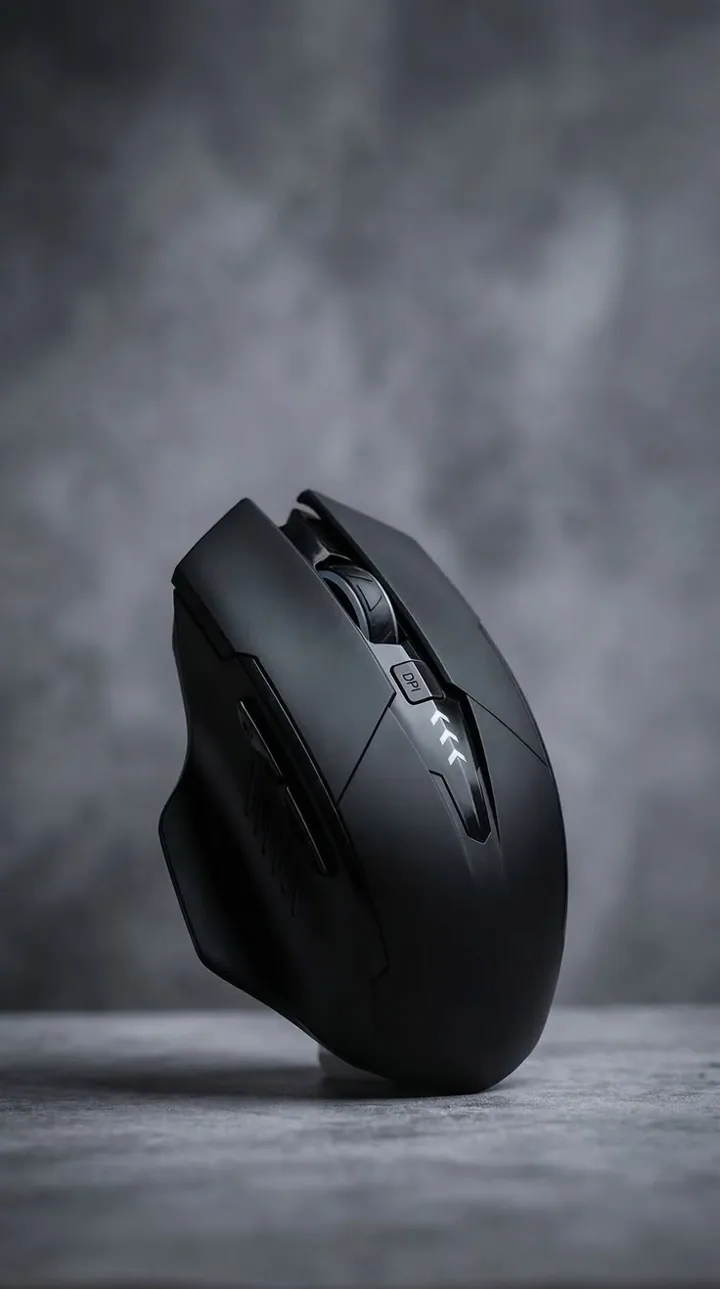
Low-latency 2.4 GHz receiver, 70-day battery life and silent switches. Built for long days.
| Connection | 2.4 GHz, BT5 |
| Battery | 70 days |
| Weight | 62 g |
Keep only the main content
Spicrawl drops the cookie banner, menus, ads and footer, and keeps the main content.
curl -X POST https://api.spicrawl.com/v1/scrape \ -H "Authorization: Bearer spicrawl_live_…" \ -H "Content-Type: application/json" \ -d '{ "url": "https://example.com/product/1", "response_format": "markdown", "main_content_only": true }'How it works
- Send a URL to
POST /v1/scrapeand choose aresponse_format. - Spicrawl fetches the page. It uses a plain request first, or a browser when you ask for one.
- You get the result in the response body, with the site's own status in a header.
curl -sS -D - https://api.spicrawl.com/v1/scrape \
  -H "Authorization: Bearer $SPICRAWL_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"url": "https://example.com/products/42", "response_format": "markdown"}'
import os, requests
r = requests.post(
"https://api.spicrawl.com/v1/scrape",
headers={"Authorization": f"Bearer {os.environ['SPICRAWL_API_KEY']}"},
json={"url": "https://example.com/products/42", "response_format": "markdown"},
timeout=120,
)
print("site status:", r.headers.get("X-Target-Status"))
print(r.text)const r = await fetch("https://api.spicrawl.com/v1/scrape", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.SPICRAWL_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({ url: "https://example.com/products/42", response_format: "markdown" }),
});
console.log("site status:", r.headers.get("X-Target-Status"));
console.log(await r.text());spicrawl scrape https://example.com/products/42 --format markdown --metaKeep your key in SPICRAWL_API_KEY and never write it into code you commit.
Output formats
| Format | Best for |
|---|---|
markdown | AI prompts, RAG and reading. Main content only by default. |
json | Apps: the content plus metadata, links or extracted fields in one object. |
html | When you need the page's markup. This is the default. |
text | The smallest output, with no formatting. |
pdf | A PDF of the rendered page. |
See website to Markdown for more on the Markdown output.
Check the result
The HTTP status is Spicrawl's. What the site answered is in X-Target-Status. A successful call looks like this:
HTTP/2 200
content-type: text/markdown; charset=utf-8
x-target-status: 200
x-engine: fetch
x-credits-charged: 1
cache-state: miss
A 403 or 503 in X-Target-Status means you got a block page, and it costs 0 credits.
Pages that need more
- JavaScript pages. Set
js_render: trueto load the page in a browser first. See JavaScript rendering. - Logged-in pages. Use a session to keep cookies between requests, for accounts you own or may use. See sessions and logins.
- Clicks and scrolling. Browser actions can click, type and scroll before the page is read. See browser actions.
- Many URLs. A batch job takes up to 10,000 URLs in one call. See batch.
What it costs
- Free during the beta, with no credit card.
- Credits per successful request: 1 for a plain request, 3 for browser rendering, 8 for full Chromium.
- Failures are free: errors, bot challenges and pages that answer with an error cost 0.
- Cap every request with
max_cost, so a call never costs more than you expect.
Good to know
- No crawling. Spicrawl does not follow links or discover pages. You send the URLs.
- Coming soon: managed proxies, stealth mode, a remote browser and extraction from a plain-language prompt. Today you can bring your own proxy at no extra cost.
- Your responsibility: only fetch pages you have the right to use. See our terms.
Frequently asked questions
What is a web scraping API?
It is a service that fetches a web page for you and returns its content in a form your code can use. You send a URL; it handles the request, JavaScript and clean-up, and returns Markdown, JSON or HTML.
How much does the Spicrawl scraping API cost?
It is free during the beta, with no credit card. Requests use credits: 1 for a plain request, 3 for browser rendering and 8 for full Chromium. Errors, bot challenges and pages that answer with an error cost 0.
Can it scrape pages that need JavaScript?
Yes. Set js_render to true and the page loads in a browser first. Start with a plain request and render only when the plain result is empty.
How do I know if the site blocked me?
Read the X-Target-Status header. The HTTP status is Spicrawl's; X-Target-Status is what the site answered. A 403 or 503 there means you got a block page, and it costs 0 credits.
Can it crawl a whole website?
No. Spicrawl does not follow links or discover pages. Send the URLs you want, one at a time or up to 10,000 in one batch call.