Free web scraping API Feed your agent live web data
Scrape, click, log in and batch up to 10,000 URLs, all through one API, CLI or MCP server.


Turn a messy web page into clean, LLM-ready text
A product page has plenty you don’t need in your data: menus, ads and styling. Drag across this example to see the text Spicrawl keeps, including the product name, price and links.
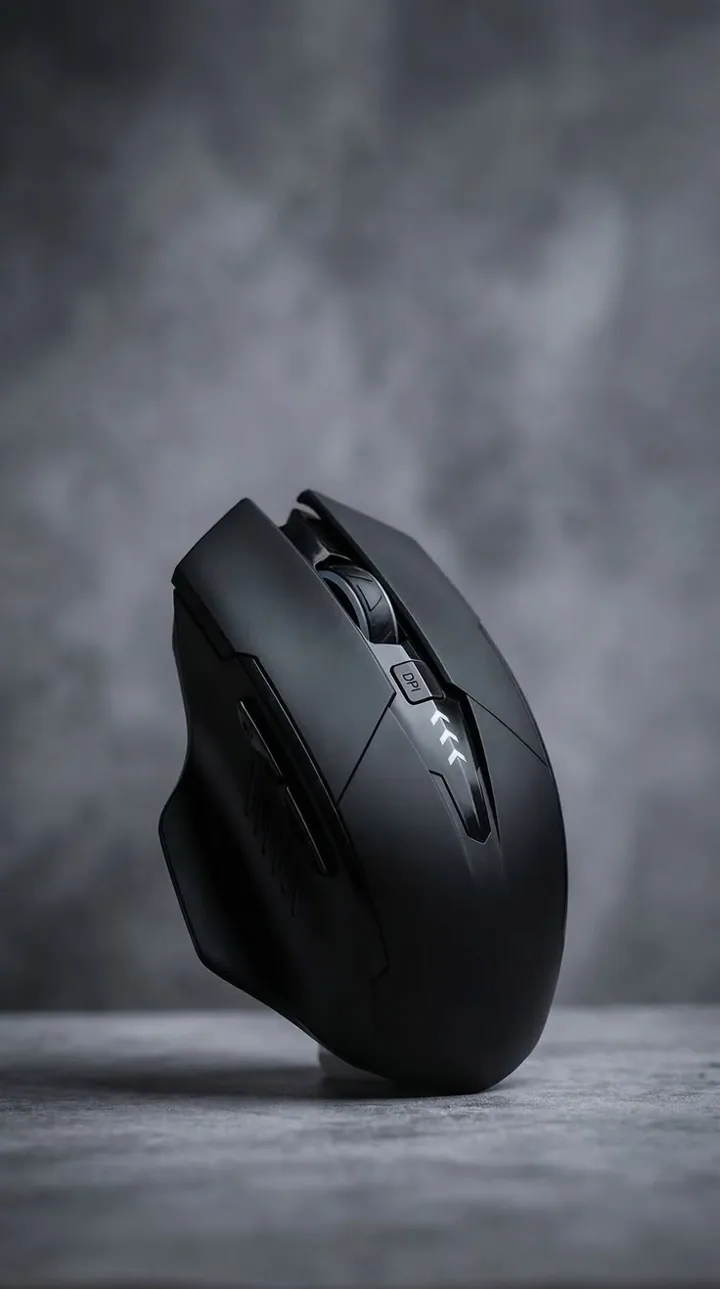
Low-latency 2.4 GHz receiver, 70-day battery life and silent switches. Built for long days.
| Connection | 2.4 GHz, BT5 |
| Battery | 70 days |
| Weight | 62 g |
Up to 97% fewer tokens than raw HTML
Same page, as raw HTML and as Spicrawl Markdown. Your agent reads the content, not the menus and scripts.
One URL in, clean data out
Send a URL. Spicrawl handles page rendering and data extraction for you.
Fetch
Send a URL and Spicrawl opens the page for you. Pages that need JavaScript are rendered in a real browser.
Links
Get the links found on a page with your results. You choose which URLs to send next.
Collect
Process multiple URLs in a single batch job. Collect results at scale without sending requests one by one.
Extract
Turn web pages into clean, usable data. Get Markdown, JSON, text, HTML, or links—ready to use.
For vibe coders and developers
Ask your AI in plain words, or write the request yourself. Same pages, same clean output.
Just ask your AI
Connect Spicrawl once, then ask in plain words: "read this page", "get the price from these 50 links". No code to write.
Set up in Claude CodeCall the API
One POST request returns Markdown, JSON or HTML. Use the CLI in scripts, or batch up to 10,000 URLs in one job.
Read the API docs
Connect your AI agent with Spicrawl MCP
A hosted MCP server. Your agent can scrape a page, run a batch, keep a session, run browser actions and check its own usage, without any glue code.
MCP endpoint: https://mcp.spicrawl.com/mcp
- Scrape
- Batch jobs
- Sessions
- Actions
- Request history
- Usage
- Docs
Scrape one URL or a whole list
Start with a single URL, then send a batch when you have more. Reuse a login session or add clicks and form inputs when the page needs them.
curl -X POST https://api.spicrawl.com/v1/scrape \ -H "Authorization: Bearer spicrawl_live_…" \ -H "Content-Type: application/json" \ -d '{ "url": "https://example.com/product/1", "response_format": "markdown", "main_content_only": true }'Get Markdown, JSON or structured data
Need text for an AI prompt, JSON for your app, or a screenshot to see the page? Pick an output and see an example below.
# Wireless Mouse — Model X**$49.00** · In stock · 4.6 (1,284 reviews)Low-latency 2.4 GHz receiver, 70-day battery lifeand silent switches.| Spec | Value || --------- | ------------ || Connection| 2.4 GHz, BT5 || Battery | 70 days |Menus, footers, ads and images removed. In our tests, 3% to 24% of the tokens of the raw HTML. Token counts are from an example page.
The full reply: status, final URL, engine, warnings, and your data. Token counts are from an example page.
Three ways to get fields: free page info, CSS rules, or a JSON Schema with selectors. Token counts are from an example page.
A list of steps to run on the page. Spicrawl runs them in full-browser rendering.
Scrape JavaScript sites, logins and dynamic pages
Wait for JavaScript, keep your session or use your own proxy. Change an option below to see how the request works.
{ "url": "https://shop.example/product/1", "mode": "auto", "cache": true, "response_format": "markdown"}- X-Target-Status
- 200
- X-Engine
- fetch
- X-Proxy-Source
- direct
- Cache-State
- hit
- X-Credits-Charged
- 1
Start with a plain request and move up to a real browser only if the site says no. You are charged for the rendering tier that worked, and a blocked or refused request costs nothing.
Render JavaScript in a real browser before the page is read. Spicrawl picks the rendering tier for you and charges for the one that served the page.
Plain requests carry a real browser’s TLS and HTTP/2 fingerprint, which gets past checks that never run JavaScript.
Use a direct connection or your own proxy with no proxy surcharge. Managed proxies and built-in country targeting are coming soon, outside the current beta.
Keep cookies and storage between requests, so a login carries over. Session requests are never served from the cache.
Click, type, select, scroll and run JavaScript before the page is read. Actions run in full-browser rendering, which Spicrawl picks for you.
Skip images, fonts and media while rendering. Pages load faster and you move fewer bytes.
Record every request the page itself made while it loaded: the API calls behind the page, not just its HTML.
On by default for up to 48 hours. A repeat is served from the cache, billed like the fetch that stored it. It saves time, not credits.
Test in the dashboard, then build with the API and CLI
Test a URL in the dashboard. When you’re ready to build, use the CLI or follow the API examples in the docs.
Try what people build with Spicrawl
Three small tools running on the Spicrawl API. Open one and paste a link.
- change-monitor.spicrawl.com
Change monitor
Paste a page and check it again later. See exactly what changed since the last check.
Try it live - price-tracker.spicrawl.com
Price tracker
Paste a product link and get its current price and currency back.
Try it live - docs2skill.spicrawl.com
Docs → Skill
Point it at a docs site and get an agent skill built from its pages.
Try it live
What you can build with a web scraping API
Common jobs people use Spicrawl for, each with a step-by-step guide in the docs.
- 01
Feed LLMs and RAG pipelines
Turn articles, docs and PDFs into clean Markdown with the navigation and ads removed, ready to chunk and embed.
Markdown for LLMs - 02
Give AI agents web access
Connect Claude Code, Cursor, Codex or your own agent to the MCP server so it can read live pages while it works.
Build with agents - 03
Collect product and price data
Pull names, prices and stock into JSON with selectors or a schema, and skip the cache when you need today’s price.
Extract structured data - 04
Scrape thousands of URLs
Send up to 10,000 URLs in one batch job, follow its progress and download the results as JSON Lines.
Run a batch job - 05
Read pages behind a login
Log in once, keep the cookies and storage in a session, and reuse it for every page that needs the account.
Use sessions - 06
Capture the data behind a page
Record the API calls a page makes while it loads and read their JSON directly, instead of parsing the HTML.
Capture network calls
Pay per page. 1,000 credits free every month.
A page costs credits only when the request works. Spicrawl picks the cheapest way to load it. No credit card, free while we're in beta.
Frequently asked questions
What is Spicrawl?
Spicrawl is a web scraping API that turns any URL into data your code or AI agent can use: clean Markdown, HTML, text, a PDF or structured JSON. You send one request to the API, CLI or MCP server, and Spicrawl picks the engine and retries for you.
What does Spicrawl mean?
The name joins "spider" and "crawl", which is why our logo is a spider. It is spelled S-P-I-C-R-A-W-L. Spicrawl is a web scraping API: you send the URLs you want, and it returns clean data.
How do I turn a website into Markdown for an LLM?
Send the URL with response_format set to markdown. Spicrawl returns the main content of the page as Markdown, with menus, footers and asides removed, which usually takes a fraction of the tokens of raw HTML. It parses PDFs too, and Markdown conversion costs nothing extra.
Can I scrape JavaScript websites?
Yes. Set js_render to true to load the page in a real browser, and wait for the content you need before it is captured. With mode=auto, Spicrawl tries a plain HTTP request first and moves to a browser only if the page needs one, and you pay only for the step that worked.
Can Spicrawl get past bot protection like Cloudflare?
Often, but not always. You can send a real browser fingerprint, render the page in a browser, or route through your own proxy, and the docs show when to use each. A bot challenge is returned as a clear error and costs nothing. Stealth mode and managed residential proxies are not available during the beta.
Can I extract structured data as JSON?
Yes, in three ways: autoparse reads the page’s own metadata, a selector map pulls exact fields, and a JSON Schema with selectors returns typed, validated output. All three are free on top of the engine price. Extraction from a plain-language description, using a model, is coming soon.
Can I scrape many URLs at once?
Yes. A batch job accepts up to 10,000 URLs per call and runs them in parallel. You check its progress, then download the results as JSON Lines. Results are kept for 72 hours.
Can I keep a login session?
Yes. Create a session and pass its id on each request to reuse the same cookies, browser storage and exit IP, so a login carries over between pages. An organization can hold up to 100 live sessions at a time.
Can I automate clicks and forms?
Yes. Browser actions can click, type, select, scroll, wait and run JavaScript on a rendered page before it is captured, with up to 50 steps per request.
Can I use proxies?
Yes. Bring your own proxy with no proxy surcharge. Managed proxies and built-in country targeting are coming soon and are not available during beta.
Can I use Spicrawl with AI agents?
Yes. The hosted Spicrawl MCP server gives agents such as Claude Code, Cursor and Codex tools to scrape pages, run batches, reuse sessions, run browser actions, and check history and usage. The spicrawl init command sets up the MCP server and an agent skill in one step. Remote browser connections are coming soon.
Why not use my AI assistant’s built-in web fetch?
Built-in fetch tools are fine for a quick look, but they often return raw or cut-off text and may not run JavaScript. Spicrawl returns clean Markdown or JSON, renders JavaScript when a page needs it, keeps login sessions, runs clicks and form inputs, and batches up to 10,000 URLs in one job. Your agent gets the content of the page, not its menus and scripts.
Which programming languages can I use?
Any language that can send an HTTP request. The docs include examples in cURL, Python and TypeScript, and there is a JavaScript and TypeScript SDK on npm (@spicrawl/sdk) for Node.js 18 and later. The spicrawl CLI works from any shell or script.
Do failed requests cost credits?
No. You pay credits only for a successful request, and the price depends on the rendering tier that ran: 1 credit for a plain request, 3 for JavaScript rendering and 8 for full-browser rendering. Errors, bot challenges and timeouts cost nothing. A result served from the cache costs the same as the fetch that stored it.
Are there rate limits?
Yes. Each API key has a request rate, each organization has a limit on requests running at the same time, and there is a monthly credit allowance. Every response reports your current limits in its headers, and a request refused by a limit costs nothing.
Is web scraping legal?
It depends on what you collect, where you are and how you use it. Scraping publicly available pages is common, but you are responsible for respecting each site’s terms, copyright and data protection laws such as GDPR, especially for personal data. If you are unsure, ask a lawyer about your specific case.
Is there a CLI or a dashboard?
Both. A CLI covers scraping, batches, sessions, logs and usage, and the dashboard has a playground, activity logs, usage and key management.
Is Spicrawl free?
Yes. Spicrawl is free while it is in beta: every account gets 1,000 credits a month, and you do not need a credit card to sign up.
Feed your agent live web data
Start with 1,000 free credits. Connect your agent in one prompt, or call the API.
How can we help?
Ask a question, suggest a feature, or report a problem.